防詐3要訣:不聽信、不操作、掛斷電話



Build a Reasoning Model (from Scratch)
BUILD A REASONING MODEL (FROM
出版日期:
2026/08/10
2,700
訂單自國外空運,約14-21個工作天(不含例假日)到貨後依序出貨。為縮短等待,建議將此商品和其他商品分開下單。
查詢門市庫存
內容簡介
Get the eBook free when you register your print book at Manning. "An exceptional deep dive into the next frontier of AI."
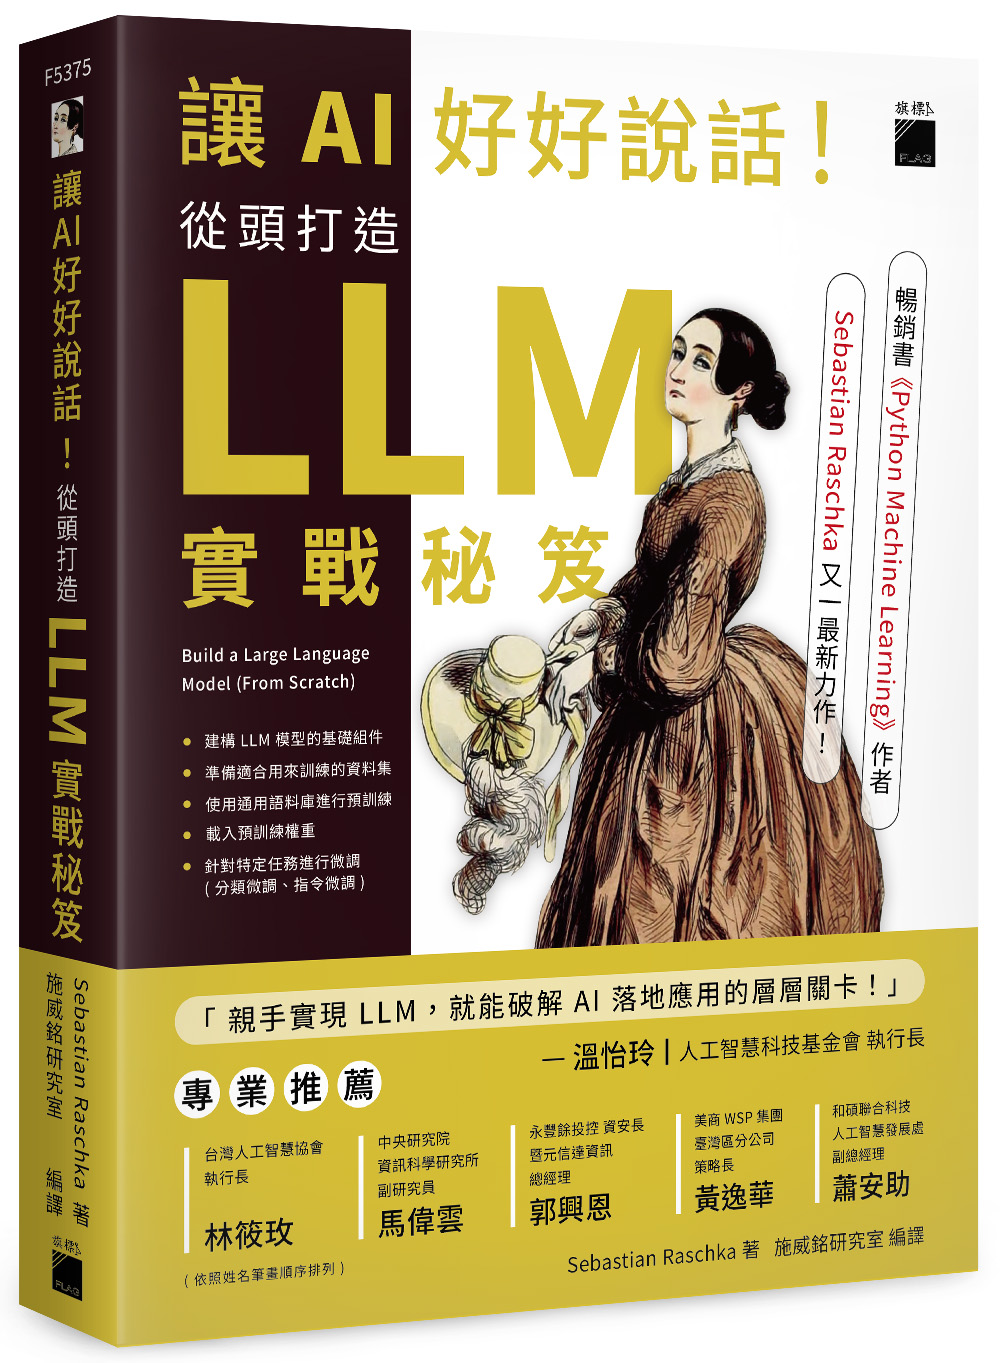
--Aman Chadha, Google This book is a practical guide to understanding how modern reasoning-oriented LLMs work by building their core methods step by step. The book tells a clear engineering story: start with a conventional pre-trained LLM, learn how text generation works, build reliable evaluation tools, improve reasoning through inference-time methods, then move into training-based approaches such as reinforcement learning and distillation. The progression is deliberate. Early chapters establish the baseline model and explain text generation, KV caching, and evaluation with math verifiers. The middle chapters show how reasoning can be improved without changing model weights, using chain-of-thought prompting, sampling, self-consistency, response scoring, and self-refinement. Later chapters move to changing the model itself through reinforcement learning with verifiable rewards, GRPO improvements, format rewards, and finally distillation from stronger reasoning models into smaller ones. The book is especially useful because it implements the core methods from scratch rather than treating them as black-box library calls. Readers see how self-consistency, self-refinement, Best-of-N, and training-based methods actually work, including their cost and latency trade-offs. It also discusses common failure modes, including cases where refinement can make answers worse. Difficult concepts such as softmax, temperature, and top-p sampling are clarified with code-linked explanations and diagrams, and visual workflows make pipelines and scoring methods easier to follow. Reading the book feels like following a guided technical build rather than a loose survey of AI topics. Each concept is introduced because the project now needs it. Diagrams, roadmaps, code listings, exercises, and repeated workflow summaries help readers stay oriented through advanced material. This structure reflects Sebastian Raschka's professional strength: explaining complex machine learning topics by making every detail concrete and showing exactly where each section fits in the larger story. He does not treat mechanisms like evaluation, log-probabilities, KL regularization, or distillation as isolated abstractions; he connects them to the goal of making reasoning models understandable and implementable. Physically and organizationally, the book has eight chapters and seven substantial appendixes. That design keeps the main narrative focused while moving supporting material like references, exercise solutions, model source code, larger models, batching, evaluation alternatives, and chat interfaces into ordered appendixes. The result is a logically flowing book that remains hands-on, navigable, and technically deep without constantly interrupting the central build. What's inside - From-scratch implementations of core LLM reasoning improvements
- Verifier-based evaluation methods
- RL with automatic verifiers for mathematics tasks About the reader For readers who know Python and have some knowledge of machine learning. About the author Sebastian Raschka is an LLM Research Engineer with over a decade of experience. He is the author of the bestselling book Build a Large Language Model (From Scratch). Table of Contents 1 Understanding reasoning models
2 Generating text with a pretrained LLM
3 Evaluating reasoning models
4 Improving reasoning with inference-time scaling
5 Inference-time scaling via self-refinement
6 Training reasoning models with reinforcement learning
7 Improving GRPO for reinforcement learning
8 Distilling reasoning models for efficient reasoning
A References and further reading
B Exercise solutions
C Qwen3 LLM source code
D Using larger LLMs
E Batching and throughput-oriented execution
F Common approaches to model evaluation
G Building a chat interface
作者介紹
Sebastian Raschka has been working on machine learning and AI for more than a decade. Sebastian joined Lightning AI in 2022, where he now focuses on AI and LLM research, developing open-source software, and creating educational material. Prior to that, Sebastian worked at the University of Wisconsin-Madison as an assistant professor in the Department of Statistics, focusing on deep learning and machine learning research. He has a strong passion for education and is best known for his bestselling books on machine learning using open-source software.
規格
誠品貨碼 /
ISBN13 / 9781633434677
ISBN10 /
EAN貨碼 / 9781633434677
裝訂 / P:平裝
頁數 / 440
重量(g) / 884.5
語言 / 3:英文
級別 / N:無
尺寸 / 23.4X18.8X2.5CM
退貨說明
退貨須知:
- 依照消費者保護法的規定,您享有商品貨到次日起七天猶豫期(含例假日)的權益(請注意!猶豫期非試用期),辦理退貨之商品必須是全新狀態(不得有刮傷、破損、受潮)且需完整(包含全部商品、配件、原廠內外包裝、贈品及所有附隨文件或資料的完整性等)。
- 請您以送貨廠商使用之包裝紙箱將退貨商品包裝妥當,若原紙箱已遺失,請另使用其他紙箱包覆於商品原廠包裝之外,切勿直接於原廠包裝上黏貼紙張或書寫文字。若原廠包裝損毀將可能被認定為已逾越檢查商品之必要程度,本公司得依毀損程度扣除回復原狀必要費用(整新費)後退費;請您先確認商品正確、外觀可接受,再行拆封,以免影響您的權利;若為產品瑕疵,本公司接受退貨。
依「通訊交易解除權合理例外情事適用準則」,下列商品不適用七日猶豫期,除產品本身有瑕疵外,不接受退貨:
- 易於腐敗、保存期限較短或解約時即將逾期。(如:生鮮蔬果、乳製品、冷凍冷藏食材、蛋糕)
- 依消費者要求所為之客製化給付。(如:客製印章、鋼筆刻字)
- 報紙、期刊或雜誌。
- 經消費者拆封之影音商品或電腦軟體。
- 非以有形媒介提供之數位內容或一經提供即為完成之線上服務,經消費者事先同意始提供。(如:電子書)
- 已拆封之個人衛生用品。(如:內衣褲、襪類、褲襪、刮鬍刀、除毛刀等貼身用品)
- 國際航空客運服務。
若您退貨時有下列情形,可能被認定已逾越檢查商品之必要程度而須負擔為回復原狀必要費用(整新費),或影響您的退貨權利,請您在拆封前決定是否要退貨:
- 以數位或電磁紀錄形式儲存或著作權相關之商品(包含但不限於CD、VCD、DVD、電腦軟體等) 包裝已拆封者(除運送用之包裝以外)。
- 耗材(包含但不限於墨水匣、碳粉匣、紙張、筆類墨水、清潔劑補充包等)之商品包裝已拆封者(除運送用之包裝以外)。
- 衣飾鞋類/寢具/織品(包含但不限於衣褲、鞋子、襪子、泳裝、床單、被套、填充玩具)或之商品缺件(含購買商品、附件、內外包裝、贈品等)或經剪標或下水或商品有不可回復之髒污或磨損痕跡。
- 食品、美容/保養用品、內衣褲等消耗性或個人衛生用品、商品銷售頁面上特別載明之商品已拆封者(除運送用之包裝外一切包裝、包括但不限於瓶蓋、封口、封膜等接觸商品內容之包裝部分)或已非全新狀態(外觀有刮傷、破損、受潮等)與包裝不完整(缺少商品、附件、原廠外盒、保護袋、配件紙箱、保麗龍、隨貨文件、贈品等)。
- 家電、3C、畫作、電子閱讀器等商品,除商品本身有瑕疵外,退回之商品已拆封(除運送用之包裝外一切包裝、包括但不限於封膜等接觸商品內容之包裝部分、移除封條、拆除吊牌、拆除貼膠或標籤等情形)或已非全新狀態(外觀有刮傷、破損、受潮等)與包裝不完整(缺少商品、附件、原廠外盒、保護袋、配件紙箱、保麗龍、隨貨文件、贈品等)。
- 退貨程序請參閱【客服專區→常見問題→誠品線上退貨退款】之說明。
付款/配送